How to Scrape Reddit: Posts, Comments & Subreddits (No Login)
Learn how to scrape Reddit posts, comments, subreddits and search results without coding, no Reddit login. 64 data fields per result, step by step.
So here you are... trying to scrape Reddit, and every tutorial says the same thing.
"Just add .json to the end of any Reddit URL!"
You try it. You get a 403. 🙃
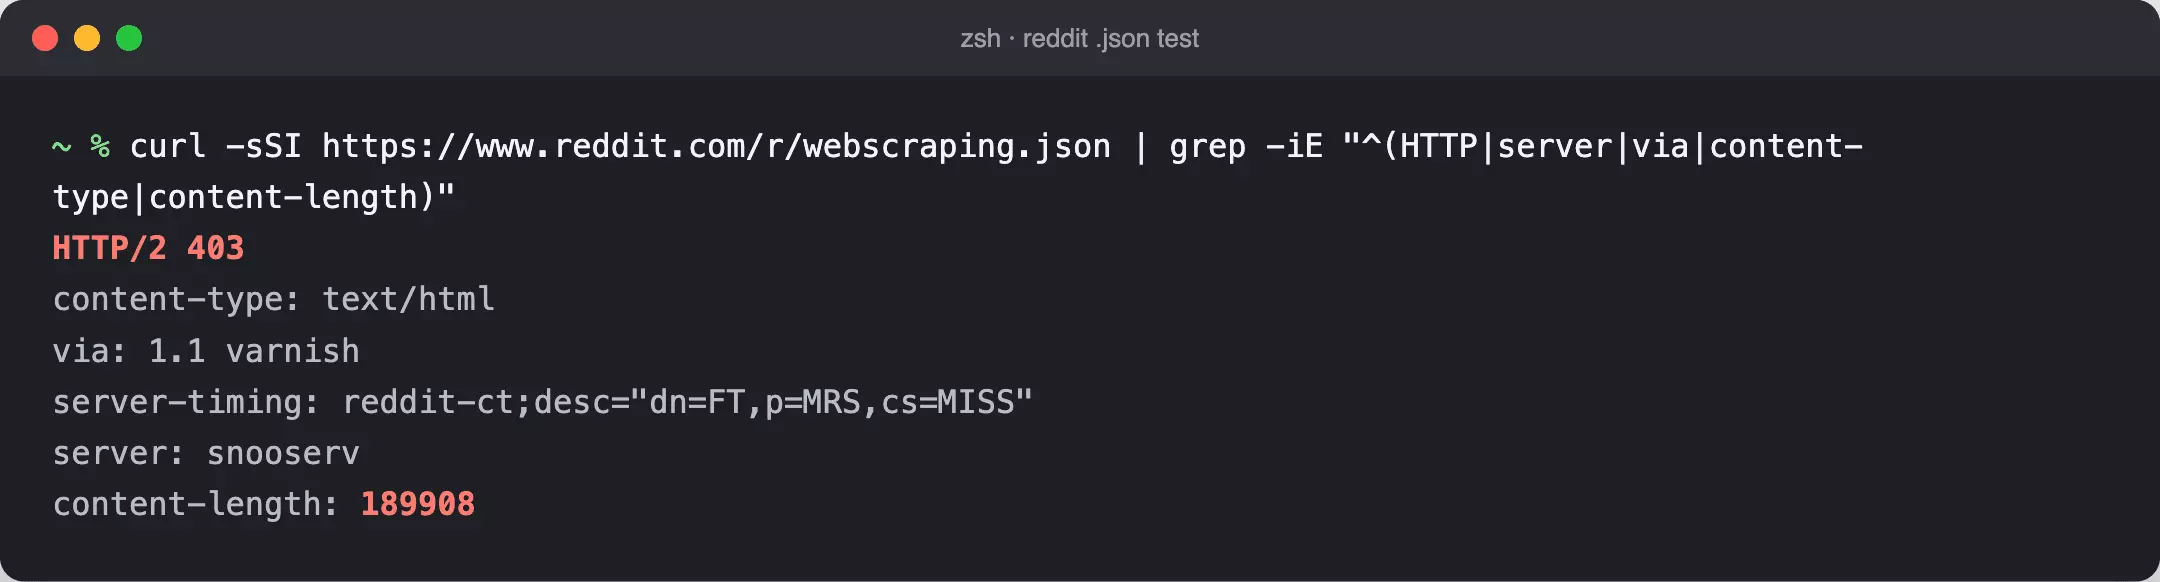
I tested it myself on 18 September 2026, with three different User-Agents. Same 403 every time, byte for byte identical.
Don't worry, I got you.
Here's a no-nerd tutorial on how to scrape Reddit posts, comments and subreddits, without coding and without logging in.
But hang on... why did the .json trick stop working in the first place?
01 / 06Does Reddit offer an official API#
Let me give it to you straight: yes, but not one you can use without OAuth and a lawyer.
Reddit used to let you append .json to any URL and get clean structured data back. No key, no account, nothing.
That ended on 28 May 2026, when Reddit posted this in r/modnews.
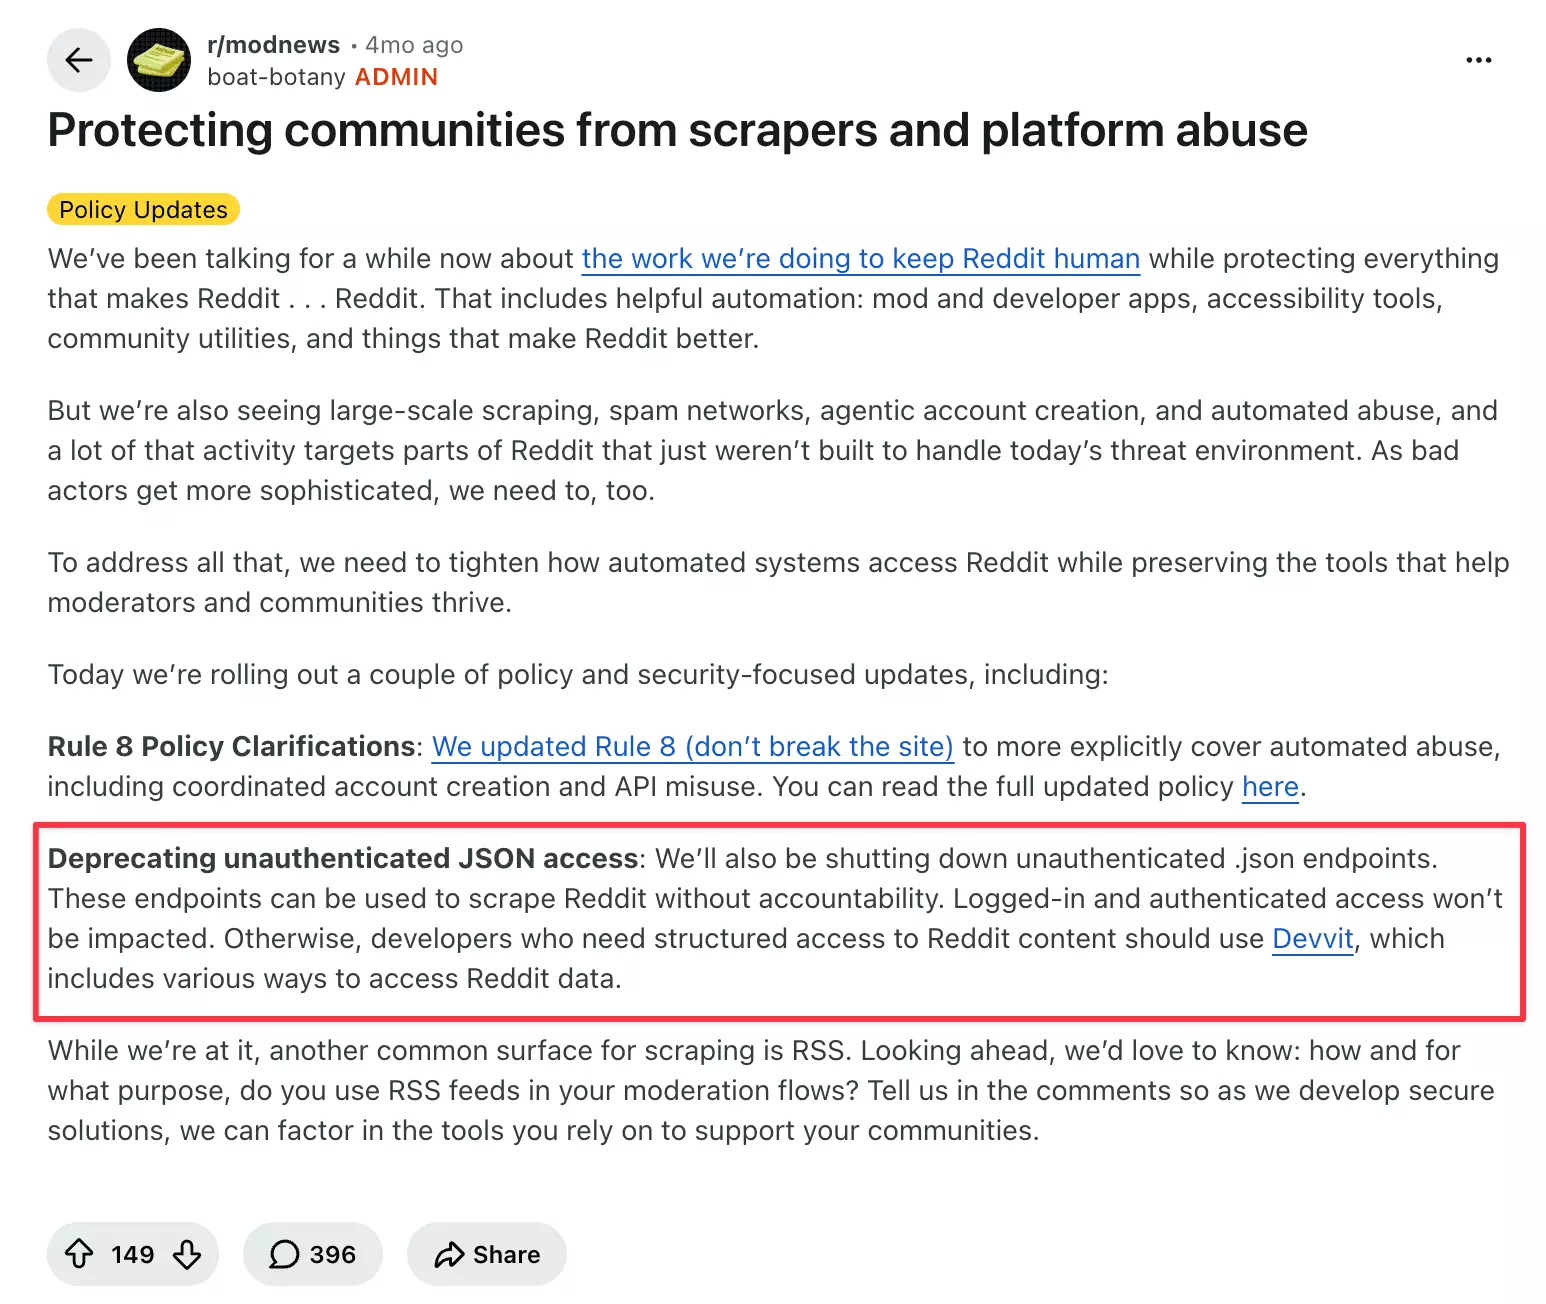
An admin clarified it the next day. Requests without OAuth or user credentials get blocked.
The first public breakage report landed on GitHub less than a day later. No migration window.
And here's the part that catches people out.
Reddit's HTML pages still return HTTP 200.
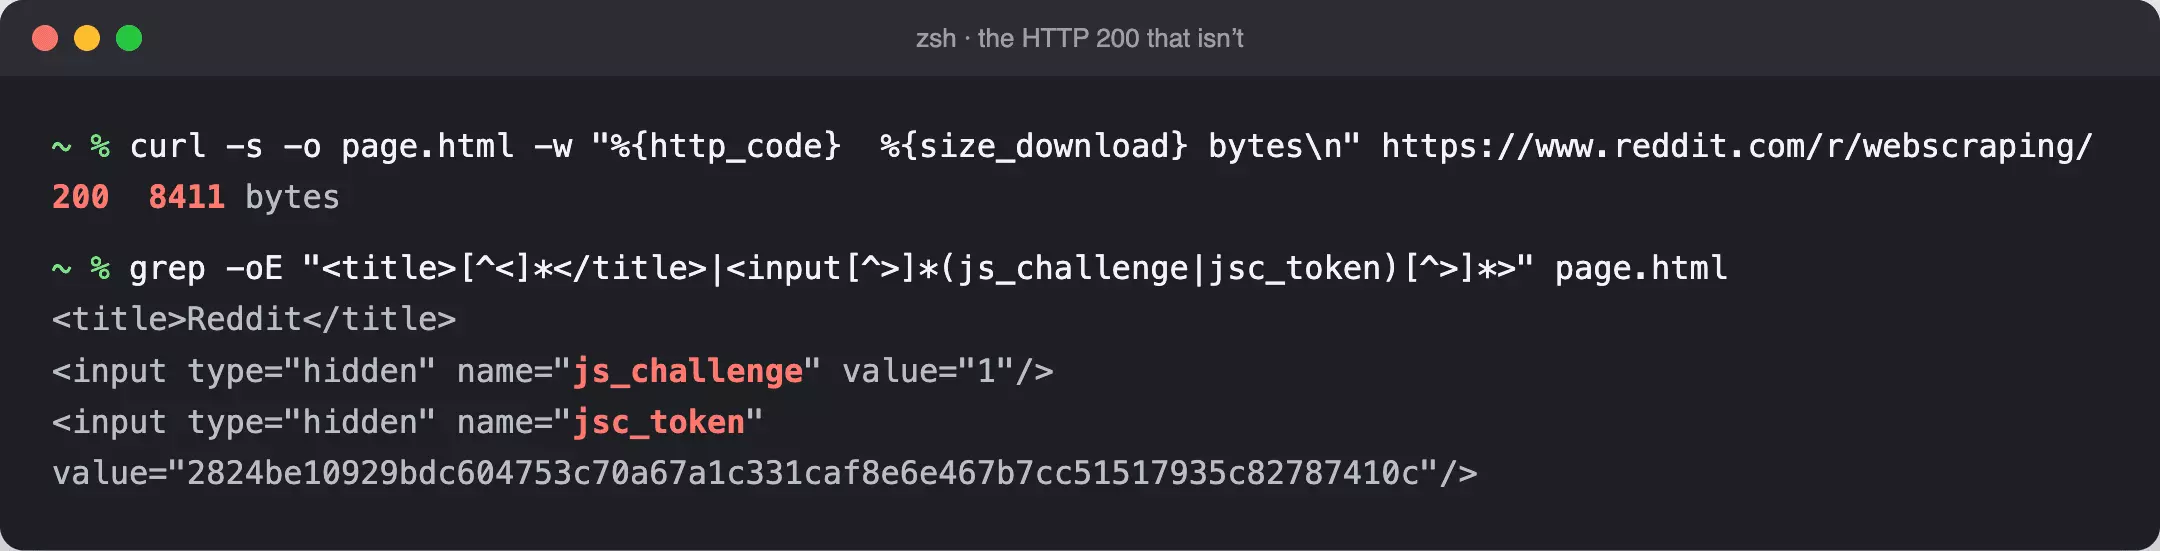
That 200 is an 8,411 byte JavaScript challenge page carrying js_challenge and jsc_token fields. Your scraper thinks it succeeded and parses exactly zero posts.
If you're checking response.status_code == 200, you will never notice.
So what about the real API?
The official Data API lives at oauth.reddit.com. It comes with strings attached:
- 100 queries per minute per OAuth client ID on the free tier
- A separate commercial agreement for "commercial purposes, research in excess of rate limits, or any use that is not expressly permitted"
- Listings cap out around 1,000 items, and comment trees truncate into
morestubs that each cost another request - Reddit is winding it down. In August 2026 the CTO announced the Public Data API is being replaced by Devvit, with new requests gradually restricted
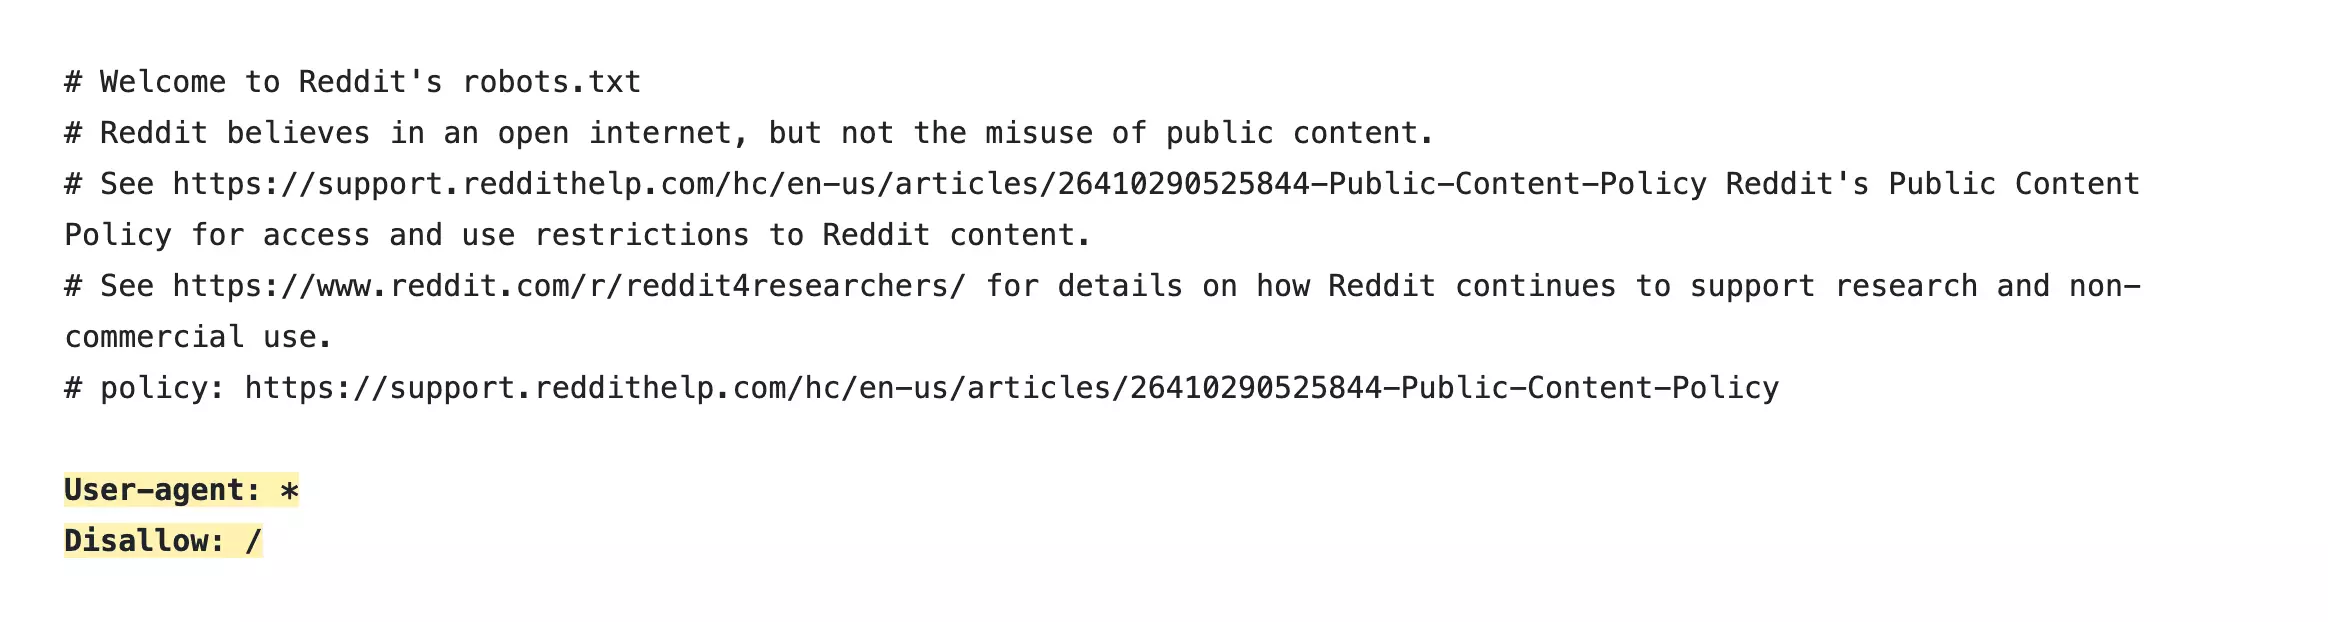
Oh, and robots.txt? Now Disallow: / for every crawler on earth. Not even Googlebot gets an exception.
And that's exactly why you need a scraper.
But how do you actually scrape Reddit at scale?
02 / 062 ways to scrape Reddit#
You've got two options:
- Build your own scraper
- Use a ready-made scraper
Build your own scraper#
This one's for the nerds. People who enjoy mass destruction.
You're not fighting a rate limit anymore. You're fighting a JavaScript proof-of-work challenge that only hands over a cookie once your code solves it.
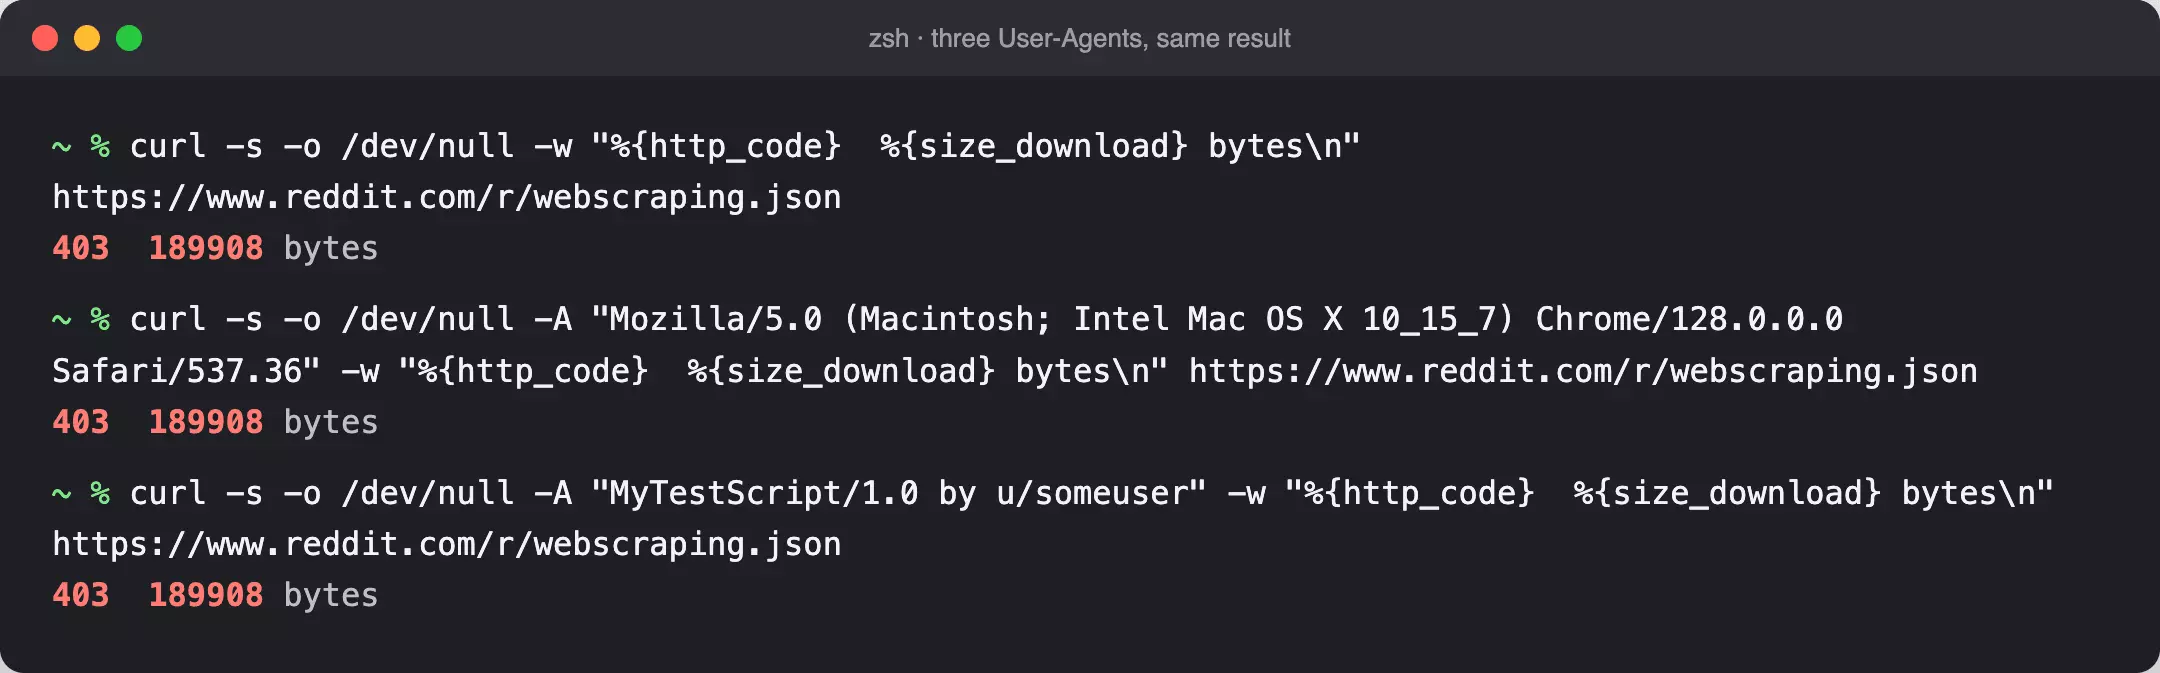
Open source maintainers shipped a workaround within 48 hours, and called it "very fragile" in their own release notes.
They were right. Reddit renamed the challenge fields in September 2026 and those workarounds broke again.
Here's what else you're signing up for:
- A polite User-Agent buys you nothing... a browser string and a descriptive
MyTestScript/1.0 by u/someuserreturned the identical 403 - Slowing down doesn't help, the block is stateless and you're refused on request number one with no
x-ratelimitheaders old.reddit.comis not an escape hatch, it never serves the challenge page at all- RSS feeds still work but give you 25 items with no score, comment count, upvote ratio or flair, and one query parameter trips the 403
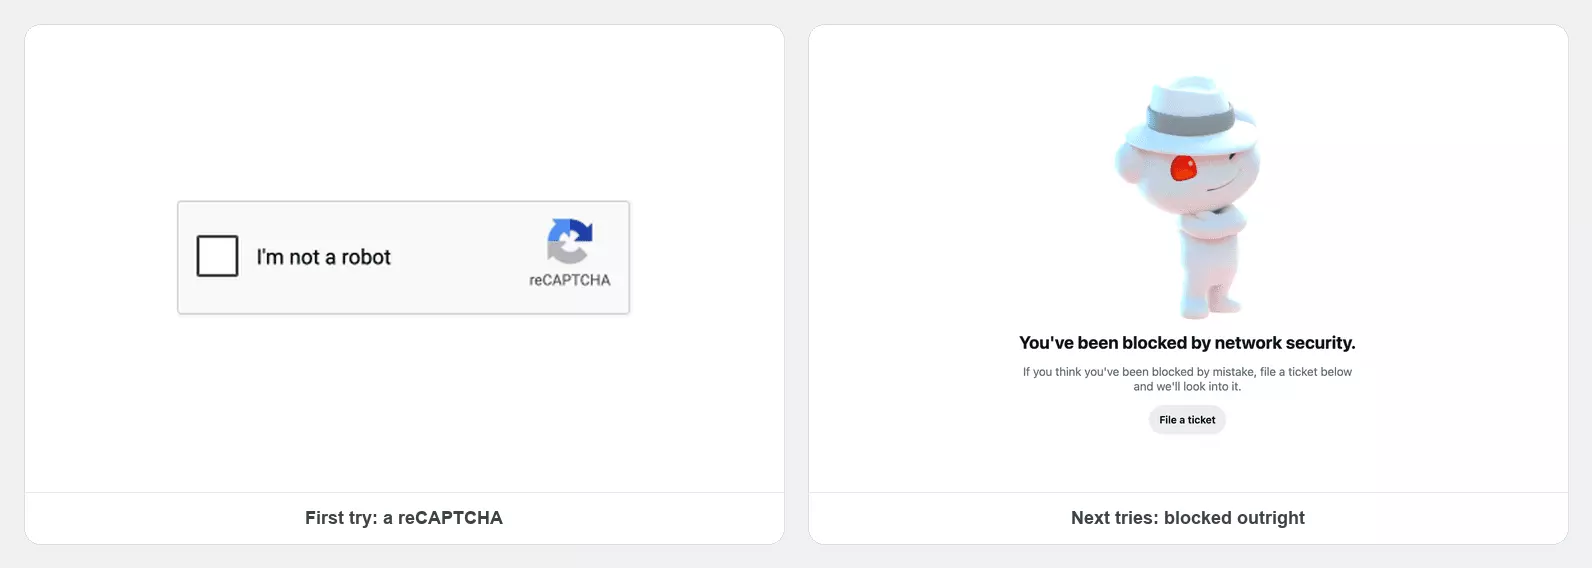
True story: even Claude couldn't grab a Reddit screenshot for this article. Reddit hit its automated browsers with a CAPTCHA, then a flat block, so I took it by hand.
Use a ready-made scraper#
This is what smart people do.
Even here you've got APIs and no-code options. APIs are for nerds. This article is no-code only.
I've already done a full scored comparison of the best Reddit scrapers. For now, here's the one I actually use.
Best Reddit scraper: lobstr.io#
lobstr.io is a no-code cloud scraping platform with 50+ ready-made scrapers. One of them is the Reddit Scraper.
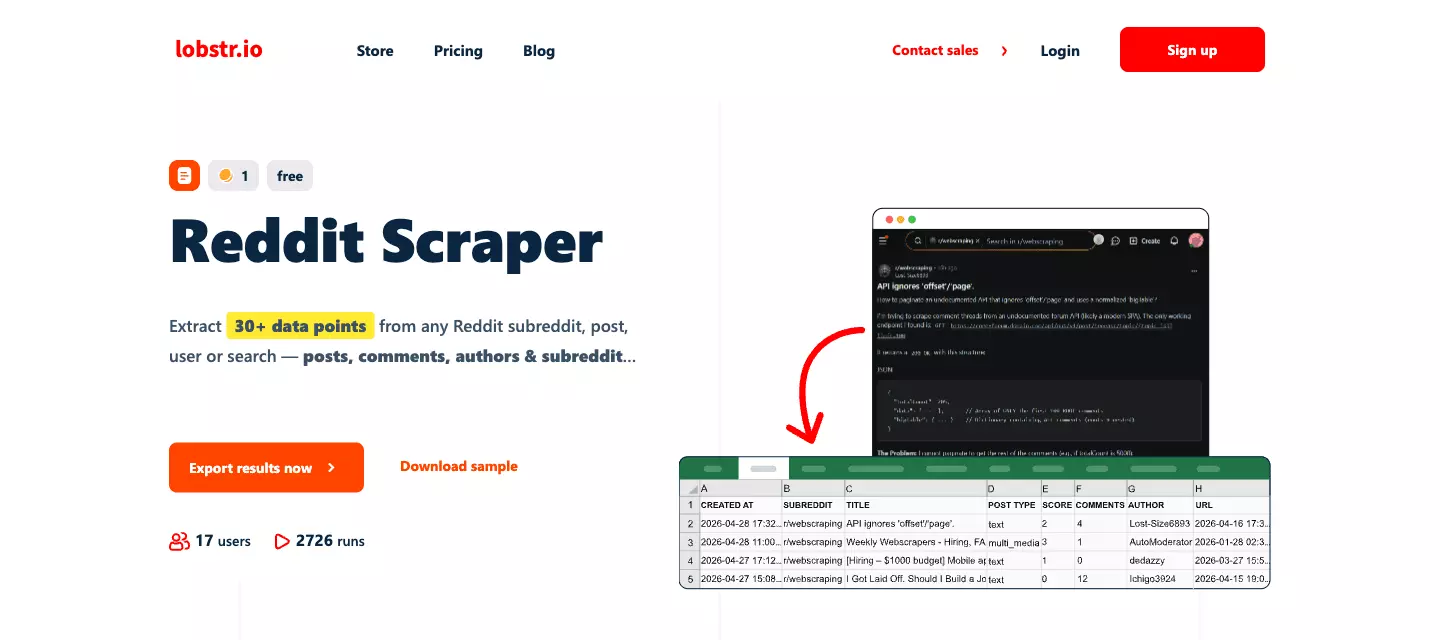
Scrape any subreddit, post, or search in minutes
Features
- No Reddit account required... no login, no cookies, no browser extension, no OAuth app to register
- 64 data points per result across posts, comments and subreddit metadata
- Five input types from one field... a post, a subreddit, a user profile, a global search or a subreddit search
- Search inside comment bodies, not just post titles, which is where people actually describe their problems
- Engagement metrics calculated for you like
score_per_hour,age_hoursandcomment_to_score_ratio - Subreddit metadata including rules and weekly active users as structured data
- Bulk upload of as many URLs as you want
- Schedule recurring runs for automated monitoring
- Export to CSV, Excel, JSON, JSONL, Google Sheets, Amazon S3 or email
- API access and an MCP server for developers
Data
| 🔗 URL | 🆔 POST ID | 📝 TITLE | 📄 BODY |

| 🏷️ POST TYPE | ⬆️ SCORE | 💬 COMMENT COUNT | 🏆 AWARD COUNT |

| 👤 AUTHOR | 🆔 AUTHOR ID | 📌 SUBREDDIT | 📌 SUBREDDIT PREFIXED NAME |

| 🆔 SUBREDDIT ID | 🏷️ FLAIR | 🌐 DOMAIN | 🗣️ LANGUAGE |

| 📅 CREATED AT | 🧬 TYPE | 💬 COMMENT ID | ↩️ PARENT ID |

| 🪜 DEPTH | ⭐ KARMA | ⭐ POST KARMA | ⭐ COMMENT KARMA |

| 📊 CONTRIBUTIONS | 🏅 TROPHIES | 📋 ACTIVE SUBREDDITS | 🛡️ MODERATED SUBREDDITS |

| 📄 SUBREDDIT DESCRIPTION | 👥 WEEKLY ACTIVE USERS | 📈 WEEKLY CONTRIBUTIONS | 📜 SUBREDDIT RULES |

| 🔖 SUBREDDIT RESOURCES | 📊 UPVOTE RATIO | 🔒 LOCKED | 📦 ARCHIVED |

| 📌 STICKIED | 🔞 OVER 18 | ⚠️ SPOILER | 🎬 IS VIDEO |

| 🖼️ IS GALLERY | 🖼️ MEDIA URL | 🖼️ THUMBNAIL | 📄 BODY HTML |

| 📏 BODY LENGTH | 📄 COMMENT BODY HTML | ⏳ AGE HOURS | 🚀 SCORE PER HOUR |

| ⚖️ COMMENT TO SCORE RATIO | 🔥 IS HIGH ENGAGEMENT | 🎖️ DISTINGUISHED AS | 📢 IS PROMOTED |

| 📝 IS SELF | 🔗 SHORTLINK | ✏️ EDITED | ✏️ EDITED AT |

| 🔄 NUM CROSSPOSTS | 🏷️ AUTHOR FLAIR | 💎 AUTHOR PREMIUM | 🥇 GILDED |

| 🌱 IS ORIGINAL CONTENT | 👥 SUBREDDIT SUBSCRIBERS | 🔄 CROSSPOST PARENT ID | 🔀 SUGGESTED SORT |
Every row is typed. A post row fills 42 of those, a comment row fills 12, and a subreddit row carries the community metadata.
Pricing
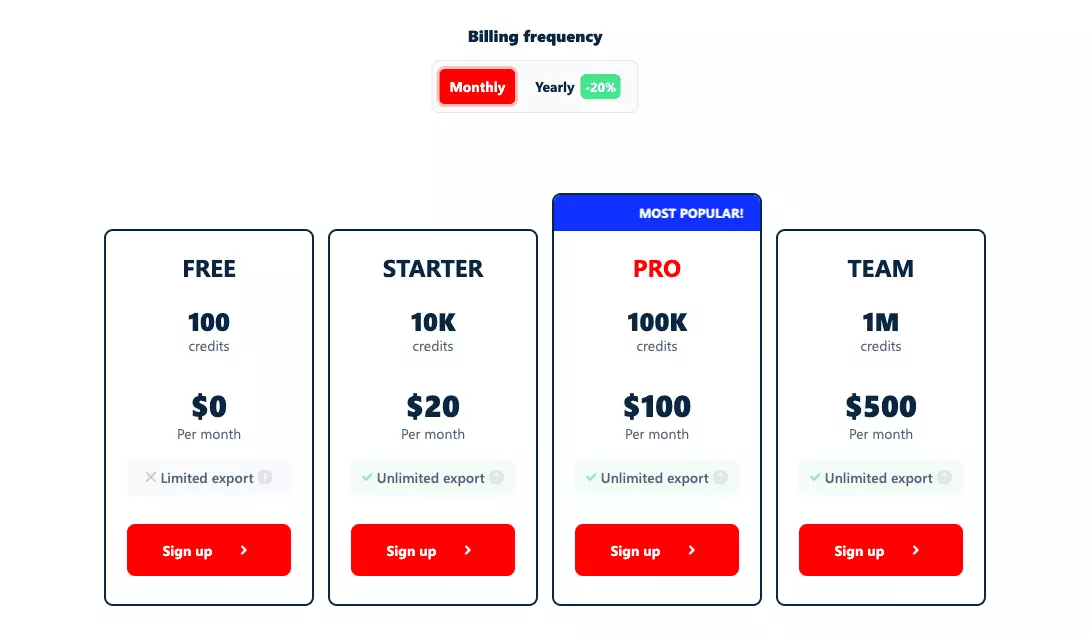
- 100 results free to start
- Starts at $2 per 1,000 results
- Drops to $0.50 per 1,000 results at scale
One result costs one credit, with no add-on functions billed on top. Empty runs cost nothing... I ran one that returned zero rows and it consumed zero credits.
So how long does it take to set up?
03 / 06How to scrape Reddit using lobstr.io [Step by Step Guide]#
Scraping Reddit with lobstr.io takes less than 2 minutes. Here's the process:
- Create a Squid
- Add tasks
- Adjust behavior
- Launch
- Enjoy
Step 1: Create a Squid#
A Squid is just a scraper instance. To create one:
- Log in to your lobstr.io dashboard
- Click the red New Squid button
- Type "Reddit" in the search bar
- Select
Reddit Scraper
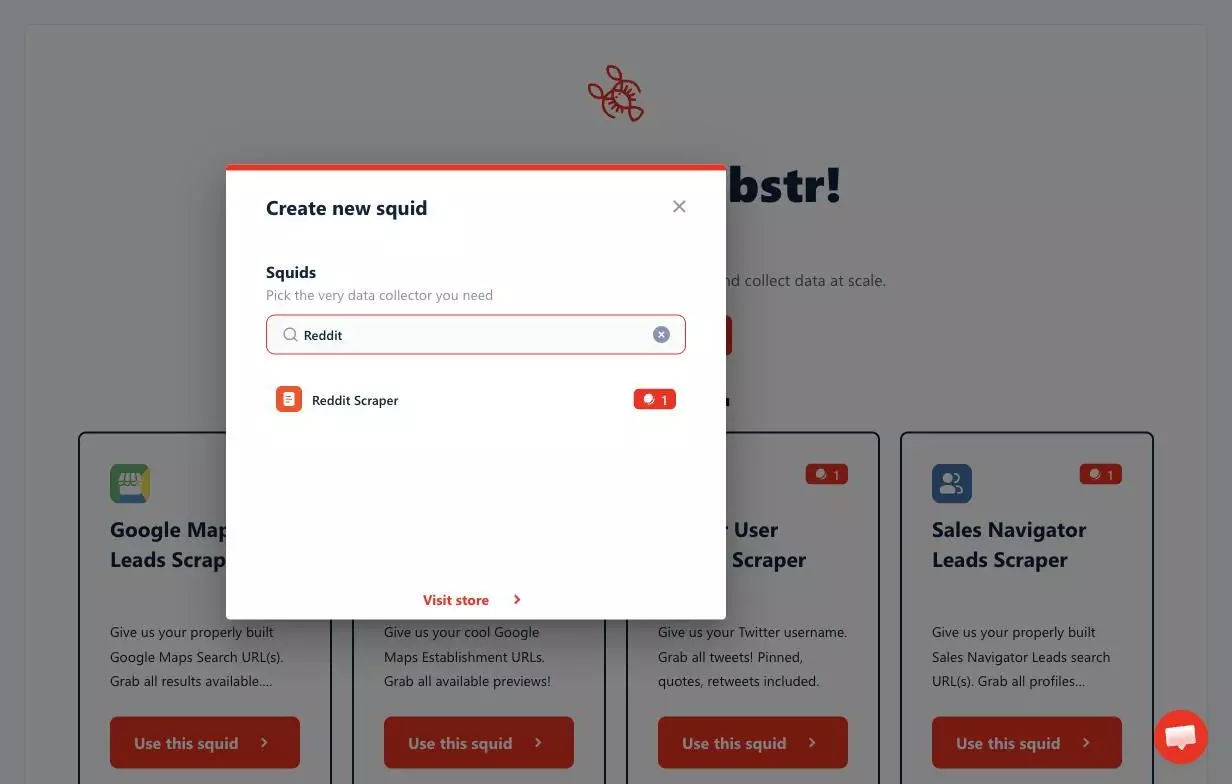
That's it. Your Squid is ready to configure.
Step 2: Add tasks#
A task is simply your input. Here, it's any Reddit URL you want to scrape.
The scraper auto-detects which kind you gave it. All five of these work:
https://www.reddit.com/r/Bitcoin/
https://www.reddit.com/r/Bitcoin/comments/1rcbgsa/crypto_beginners/
https://www.reddit.com/user/thisisbillgates/
https://www.reddit.com/search/?q=bitcoin
https://www.reddit.com/r/Bitcoin/search/?q=lightning
Paste a URL in the Url field and hit Add +.
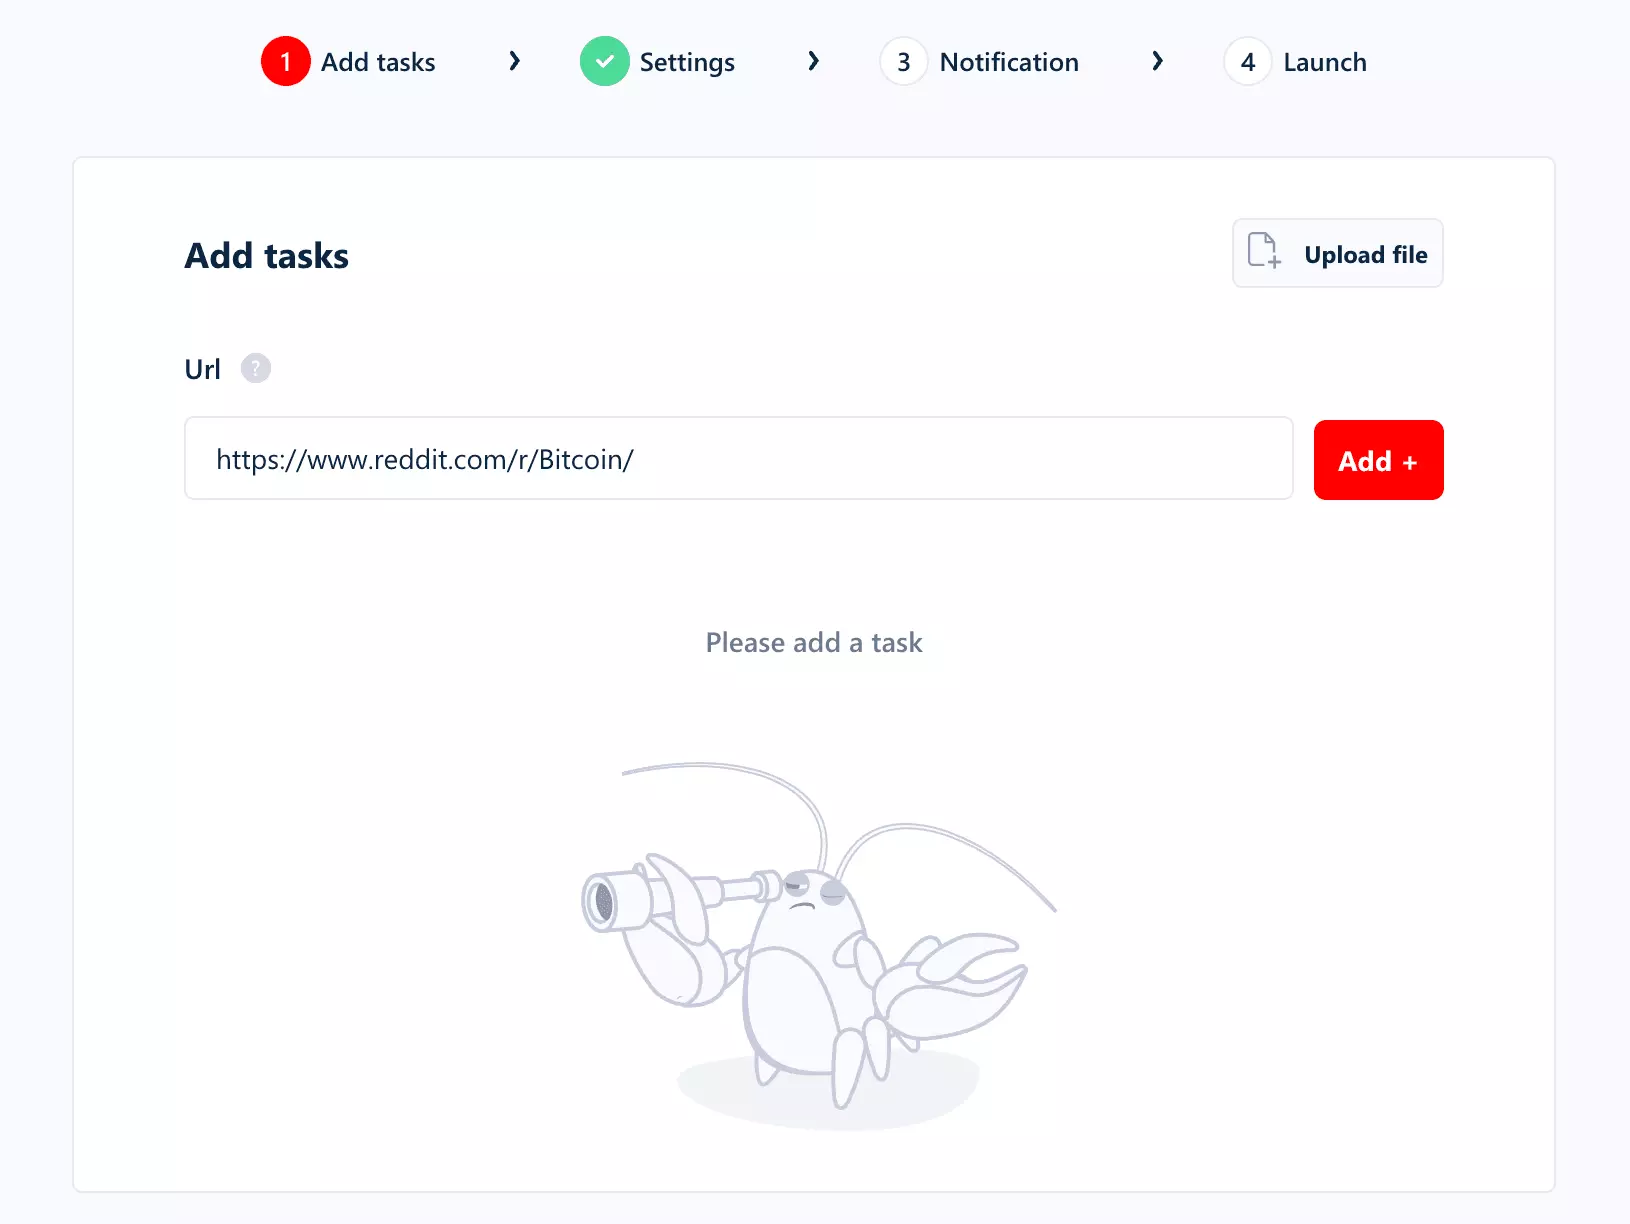
Got hundreds of subreddits to monitor? Save them in a TXT or CSV file and hit Upload file instead.
Pro tip: comments only come from post URLs, the ones with
/comments/in them. Feed it a subreddit URL and you'll get that subreddit's posts plus one metadata row, but no comments. This is the single most common mistake people make with this scraper.
Once your tasks are added, click Save to move on to Settings.
Step 3: Adjust behavior#
The Settings tab controls how your scraper behaves.
I'm not going to bore you with every option. Let me cover the ones you'll actually use.
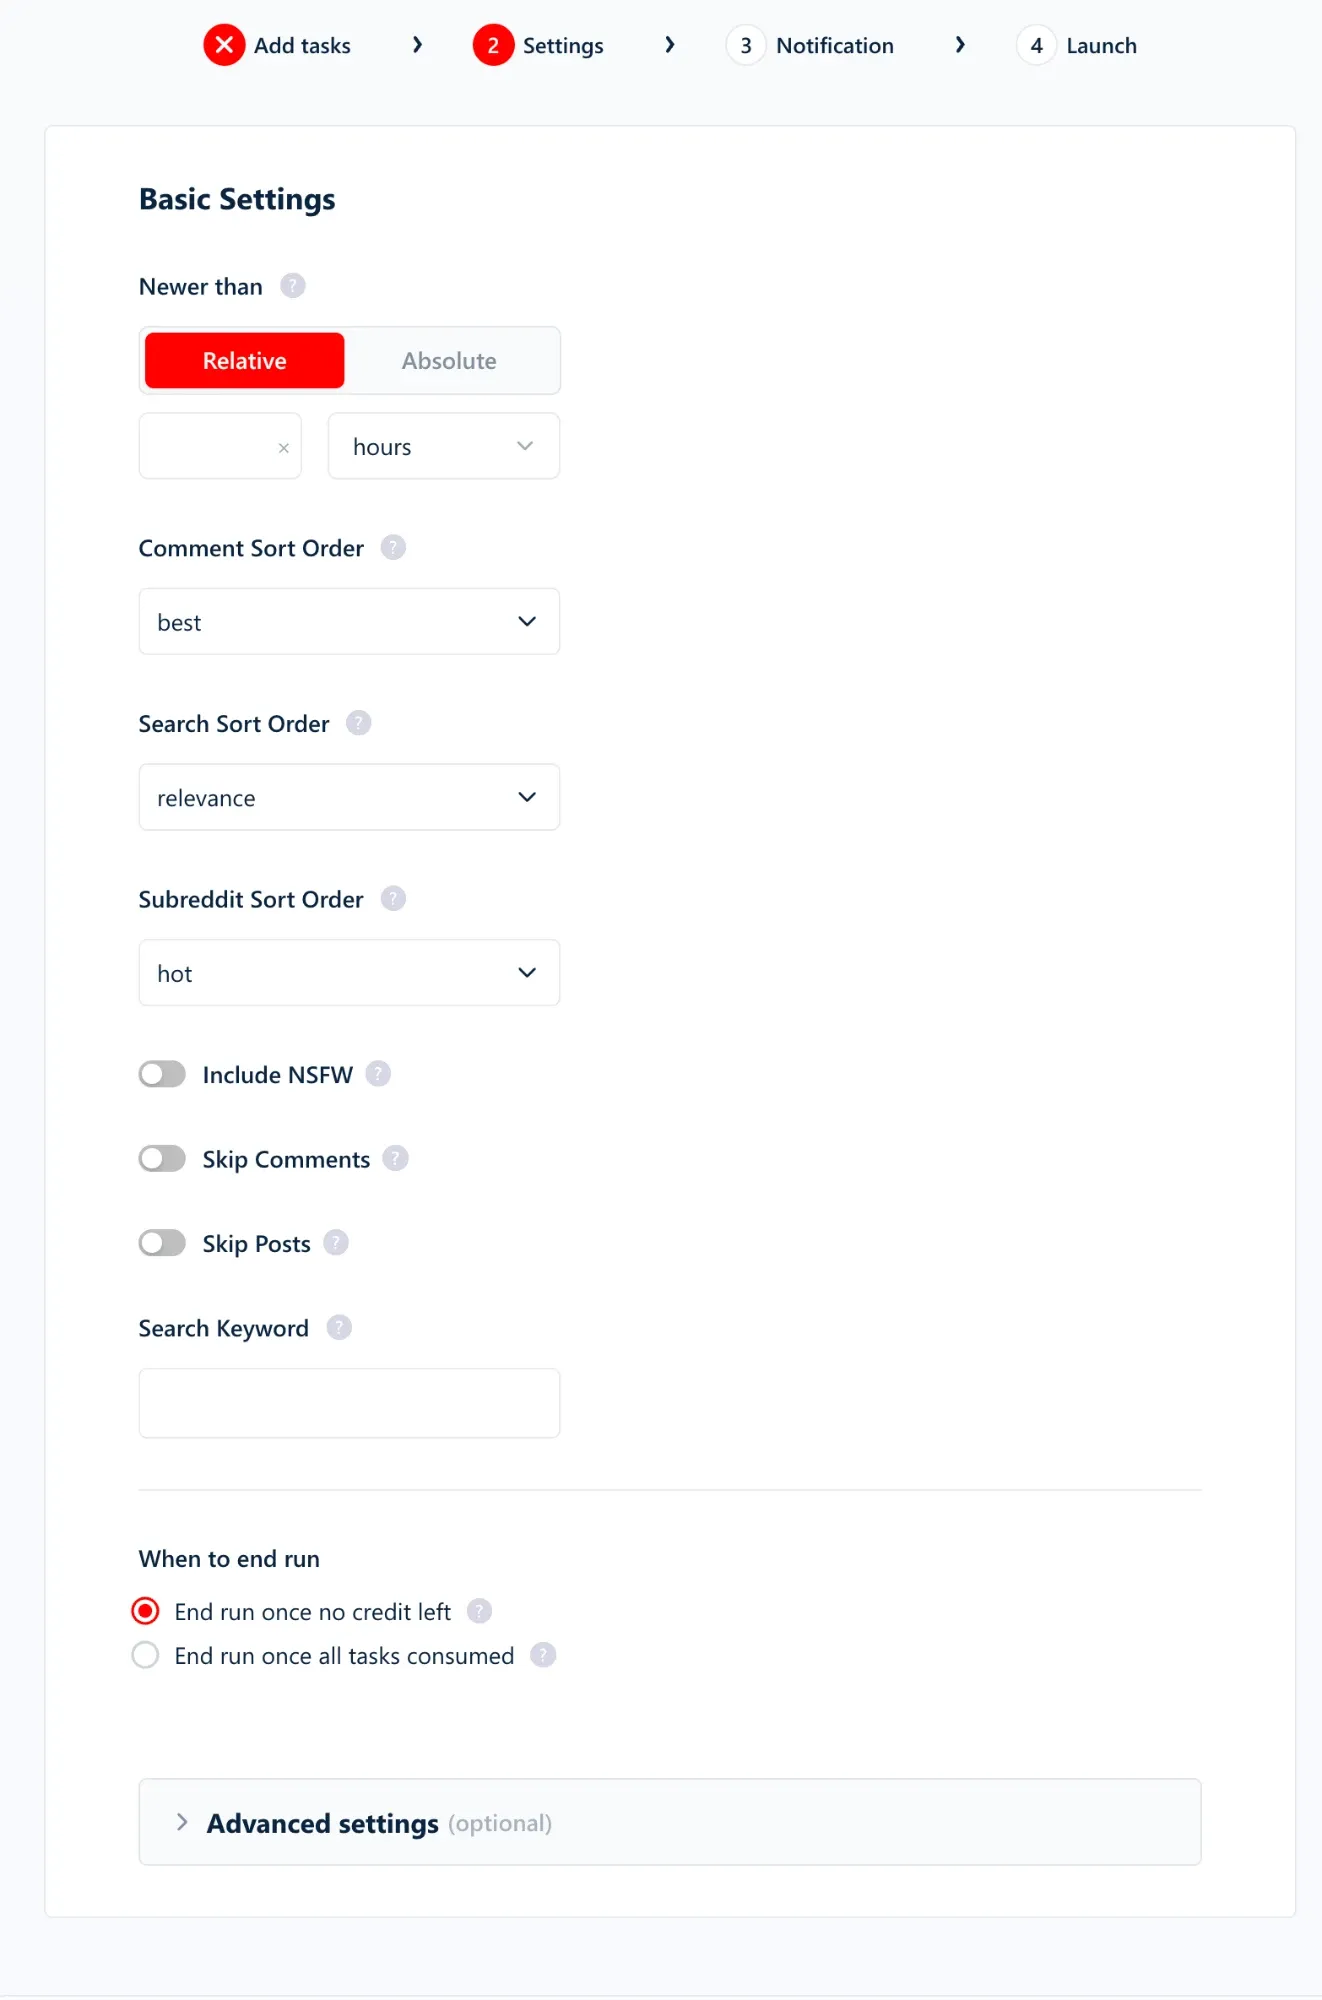
Newer than... stops the scraper at content older than your threshold, relative or absolute.
Subreddit Sort Order... controls which posts you get. Defaults to hot.
Search Keyword... drop a keyword here alongside a subreddit URL and the search scopes itself to that subreddit automatically.
Skip Comments... comments are collected by default, so flip this on if you only want post rows.
Watch out for this one. If you sort a subreddit by
hotand then set a short Newer than window, your run can come back empty. Hot posts are often days old, so the time filter eats all of them. Switch Subreddit Sort Order tonewwhen you want recent content.
When to end run lets you choose between stopping once credits run out or once all tasks are consumed.
Now open Advanced settings.
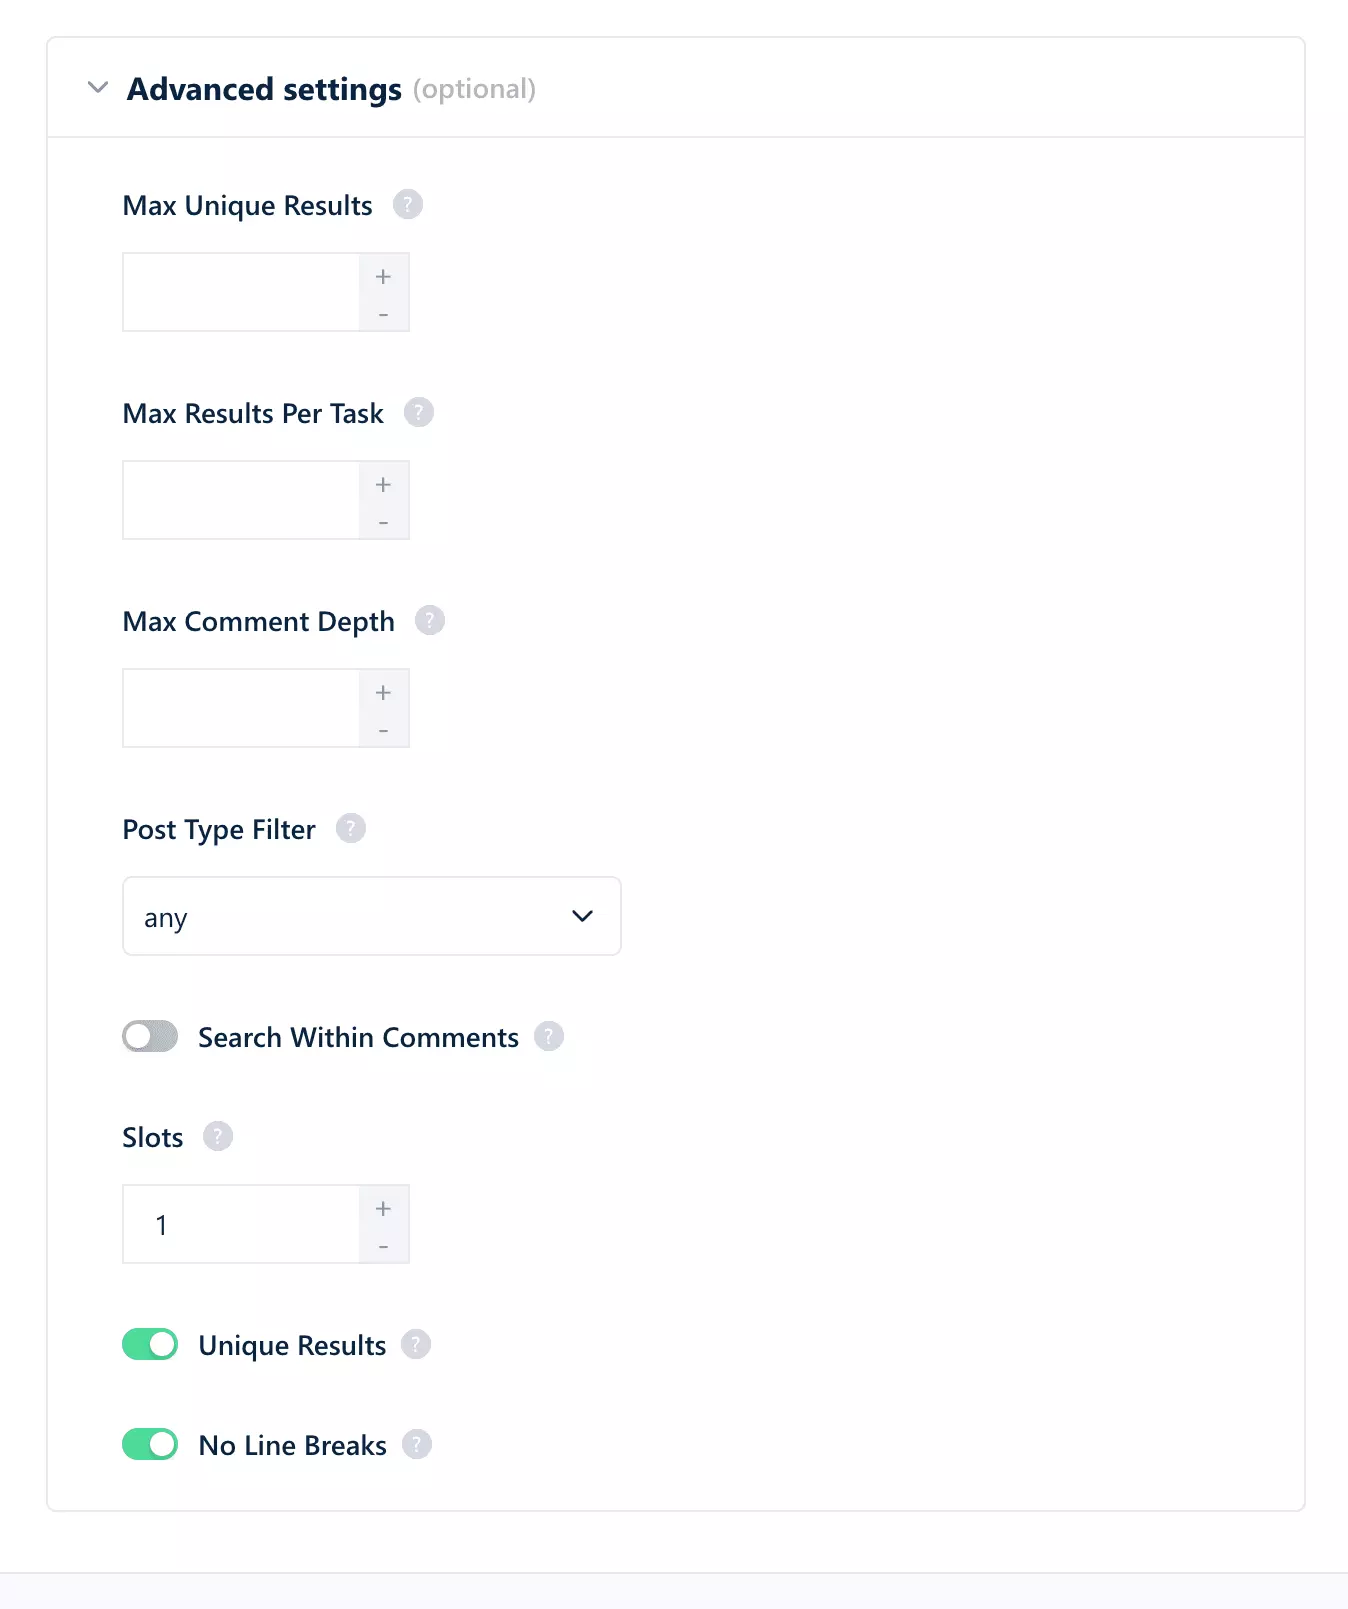
Max Results Per Task caps rows per URL, Max Unique Results caps the whole run, and Max Comment Depth controls nesting.
Search Within Comments is the one I'd pay attention to. Flip it on and Reddit searches comment bodies instead of post titles.
Slots controls concurrency, up to 20 on this scraper, defaulting to 1.
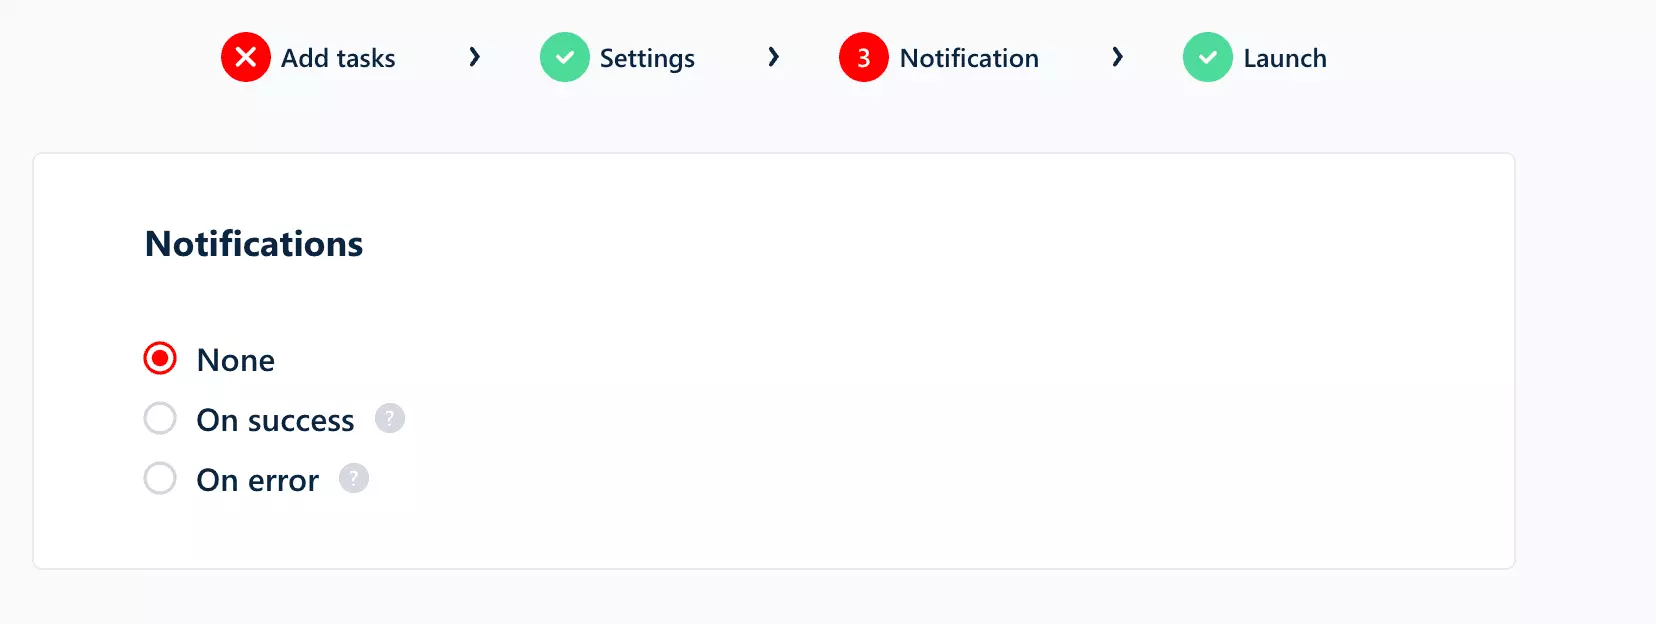
Next is the Notification tab, where you can get an email when a run finishes or errors out.
Step 4: Launch#
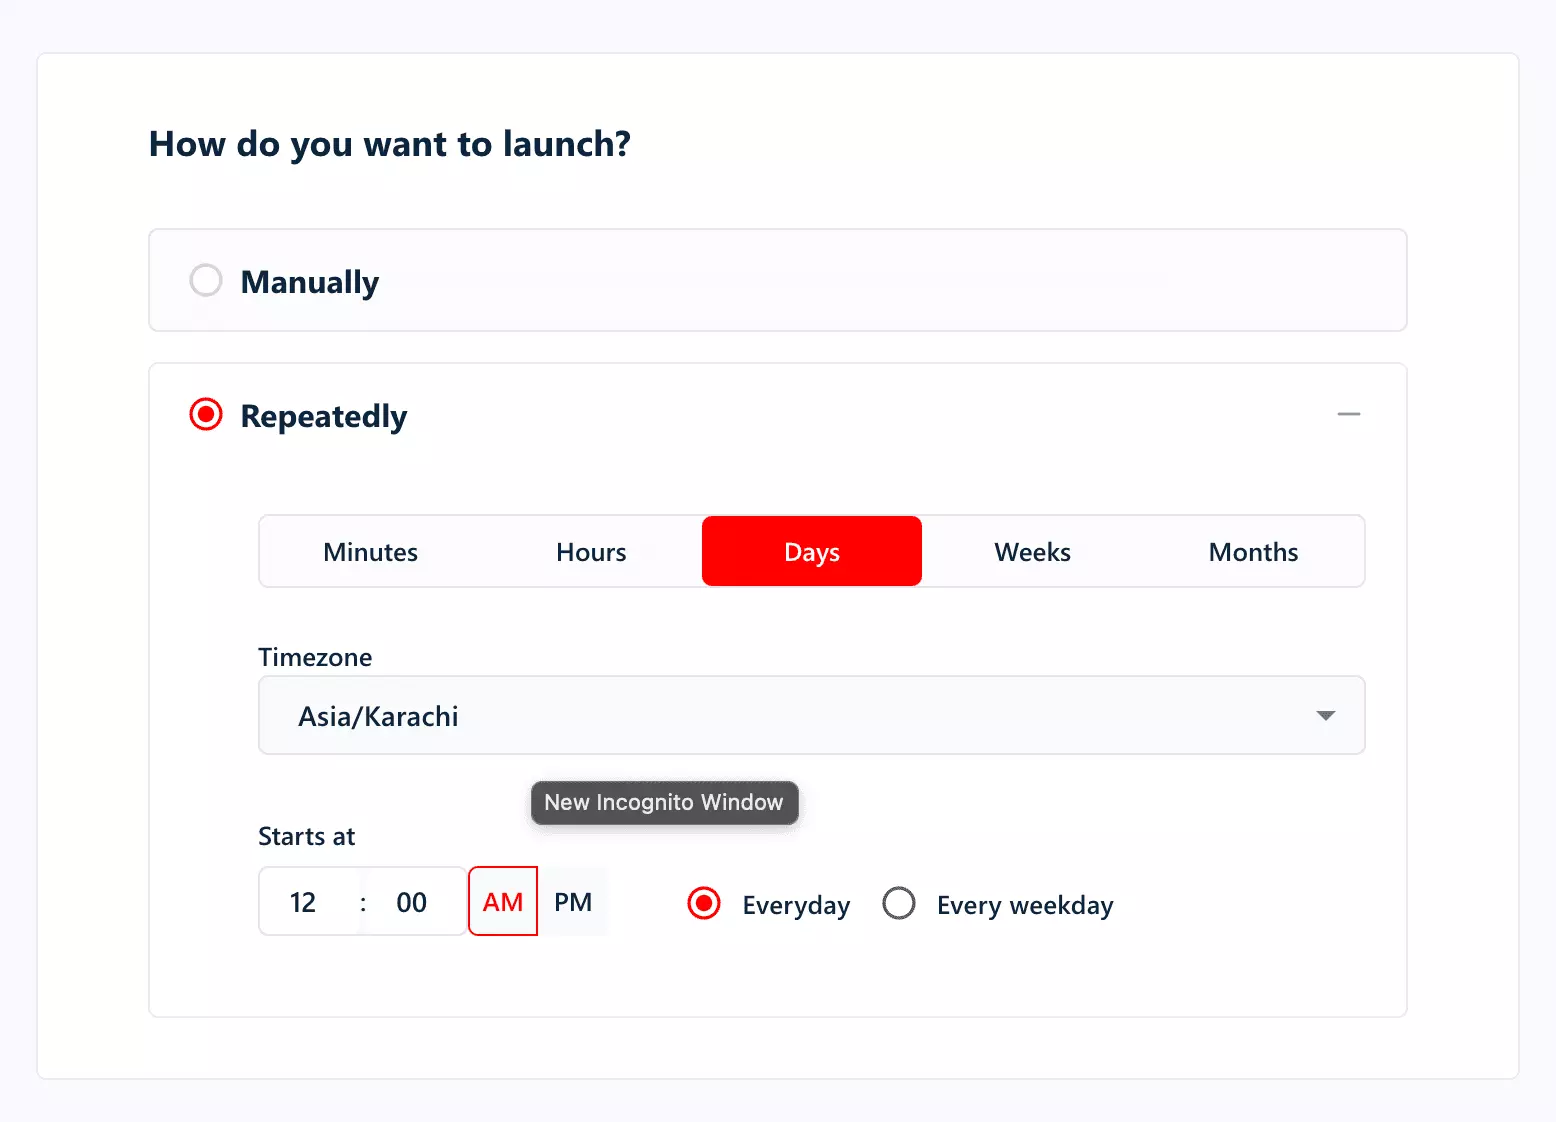
In the Launch tab you've got two options:
- Manually
- Repeatedly
Manually means instant launch. Leave it selected, click Save & Extract, confirm with Yes, and the scraper starts pulling data.
But what if you want to track a subreddit over time?
That's where Repeatedly comes in.
Set an interval in minutes, hours, days, weeks or months, pick a timezone and start time, then choose Everyday or Every weekday.
Perfect for watching a subreddit for brand mentions as they appear.
Step 5: Enjoy#
Once a run finishes, hit download and export your results as CSV, Excel, JSON or JSONL.
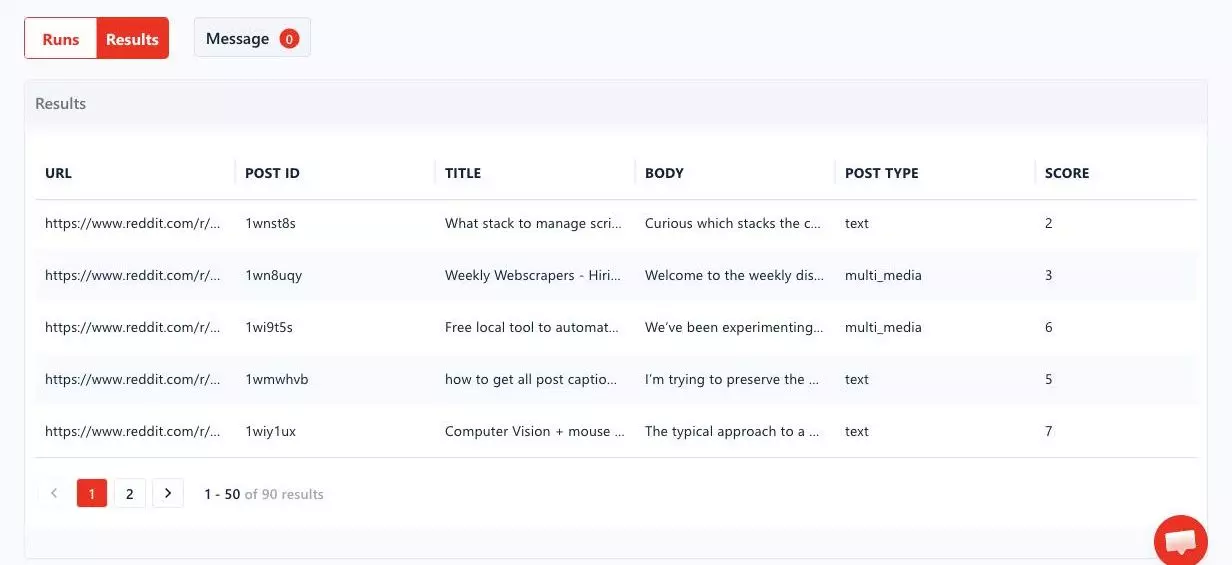
Filter the type column to split posts, comments and subreddit rows.
👉 How to download your results
But downloading a file manually every run? No thanks.
lobstr.io automates delivery. Click the Delivery icon and pick your method.
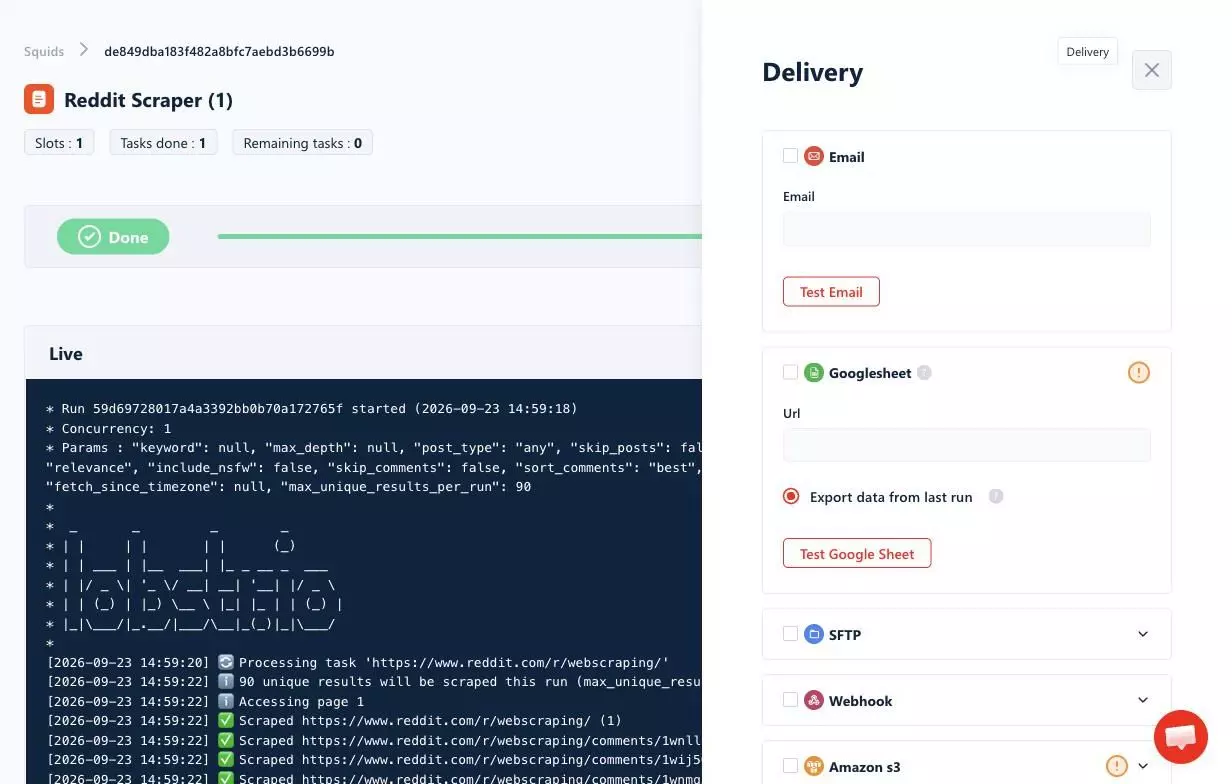
Google Sheets is my personal favorite. You can also push to Amazon S3, or just add an email address and get a CSV in your inbox after every run.
Results stay downloadable for 28 days on paid plans and 7 days on the free plan, so set up automated delivery if you want to keep them longer.
So you've got the data. Now what?
04 / 06What can you do with scraped Reddit data#
You can wire the whole thing into Make, n8n, or the REST API and never touch the dashboard again.
Or skip all of that and hand the scraper to your AI agent. lobstr.io's MCP server plugs into Claude, ChatGPT, Cursor or VS Code with one URL, and you sign in with your lobstr.io account, no API key.
If your client reads a config file, this is the whole setup:
{
  "mcpServers": {
    "lobstr": {
      "url": "https://mcp.lobstr.io/mcp"
    }
  }
}
In Claude it's even simpler... Settings → Connectors → Add custom connector, paste the URL, done. Reading is free, and your agent asks before any run spends credits.
Connect lobstr.io to your AI agent
Here's what I'd actually do with it.
1. Pain point research#
This is the one I use constantly, and I'll be honest with you... I used this exact scraper to research the article you're reading right now.
Not through the dashboard though. I drove it through lobstr.io's MCP server straight from my AI client, searching subreddits and reading results without leaving the conversation.
Turn on Search Within Comments, give it a keyword, and you get threads where people describe their problems in their own words. That's your content calendar and product roadmap in one export.
If you want me to cover how to use lobstr.io's Reddit MCP for any of these workflows, ping me on LinkedIn.
2. Brand and competitor monitoring#
Schedule a keyword scoped to the subreddits your customers live in, set Notification to fire on success, and pipe it to Sheets.
You'll spot a complaint thread before it reaches your support inbox.
3. Trend detection without the math#
score_per_hour, age_hours, comment_to_score_ratio and is_high_engagement are calculated for every row.
You don't compute velocity from timestamps. It's already in the export.
4. Community research before you post#
The subreddit row hands you subreddit_rules and subreddit_resources as structured data, plus weekly_active_users.
Read the room before you post into it.
5. Feeding an AI agent#
No Reddit account means no login step to automate and nothing to keep alive.
Connect it to Claude or ChatGPT and your agent runs the scraper itself.
Need more ideas? Here's a Reddit topics scraper use case to get you started.
05 / 06FAQs#
Is it legal to scrape Reddit#
Not a crime, but it does breach Reddit's User Agreement. Section 7 bars collecting data "by any means (automated or otherwise)" without a separate agreement, and robots.txt now disallows every crawler.
After Van Buren (2021) and hiQ v. LinkedIn (2022), the criminal route for reading public, logged out pages is effectively closed. The live risk is civil, and Reddit is currently suing Anthropic on contract and unjust enrichment grounds, plus SerpApi and others on a DMCA anti-circumvention theory.
Risk concentrates on logging in, defeating controls and reselling data. Not on reading. I've covered this properly in is data scraping illegal? and across our legal series.
This isn't legal advice. Talk to a professional if compliance matters to you.
Does the Reddit .json trick still work#
No, it returns a 403 to anonymous clients. Reddit announced the shutdown on 28 May 2026 and breakage was reported publicly within a day. api.reddit.com is gone too, and old.reddit.com just redirects you to a login.
Do I need a Reddit account or an API key#
Neither. No login, no cookies, no browser extension, no OAuth app. I ran this scraper with no account attached and it worked fine.
I scraped a subreddit but got no comments, why#
Comments only come from post URLs, the ones containing /comments/. A subreddit URL returns its posts plus a single subreddit metadata row. Feed the post URLs in to collect comment rows.
How much does it cost#
$2 per 1,000 results on Starter, dropping to $0.50 per 1,000 at scale. One result is one credit, there are no add-ons to bill on top, and runs that return nothing cost nothing.
How fast is it#
Up to 280 results per minute. A run can use up to 20 Slots of concurrency, though the Slots field defaults to 1.
Can I schedule it#
Yes, right from the Launch step. Minutes, hours, days, weeks or months, with a timezone and start time. No manual run required first.
Why not just use Reddit's official API#
Because it needs OAuth and a commercial agreement. The Data API Terms require a separate agreement for commercial use, and the free tier caps at 100 queries per minute. Reddit is also winding the Public Data API down in favour of Devvit.
06 / 06Conclusion#
That's a wrap on how to scrape Reddit posts, comments and subreddits, without coding and without ever logging in.
The .json era is over. But the data is still public, still readable, and still the most honest research material on the internet.
If you want me to cover a related topic, or walk through driving this scraper entirely through MCP, ping me on LinkedIn. 🦞